Deep Learning vs. Rule-Based Algorithms, When to Use Which
ALGORITHM
Rules read the hole diameter in 1.6 μm steps, and learning takes the scratches whose shape changes every time.
Watching one black matte molded cover with the same camera, I calculated how finely rules can measure and how long it takes to collect defect images for training.
About 11 min read
When a new inspection station is planned, the first question in the room is whether to use deep learning1 or whether rule-based2 judgment, made with rules people write, is enough. The target here is a black matte ABS molded cover. A matte surface scatters incoming light in all directions, so there are almost no blown-out hotspots, but the black pigment absorbs most of the light, so I assume a diffuse reflectance of around 5 %. Two things need checking: whether the fastening hole diameter falls within 3.00 ± 0.05 mm, and whether the surface carries a scratch 50 μm wide or wider.
Hand both items to a trained model and the station has to wait until defect images pile up. Bind both with rules and the scratches, whose shape changes every time, leak out between the conditions. The first is the cost of a delayed start, and the second is the cost of scratched covers mixing into the good-parts box and reaching the customer. Which one hurts more differs from plant to plant, but both are costs you can put a number on before the setup begins.
I settle this choice with two calculations: how many μm I can trust when rules do the measuring, and how much production time it takes to collect defect images for training. The camera is assumed to be a 2,448 × 2,048 px sensor with 3.45 μm pixels and a 25 mm lens, and the field of view is set at 40 mm across.
A decision you can write as a number ends with rules
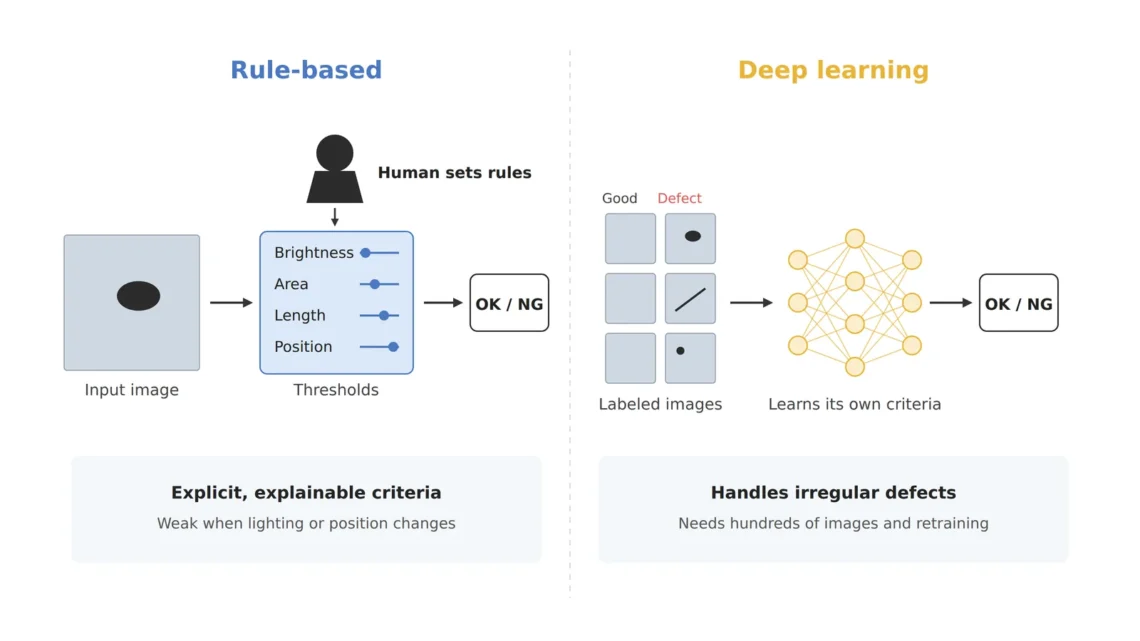
Rule-based inspection separates good from bad with numbers a person sets, such as a brightness threshold, an area, a length or a position. Blob analysis3, which flags a dark region once it clumps over a certain number of pixels, template matching, which overlays a reference shape, and edge detection, which finds boundaries where brightness changes sharply, all belong here. When a decision comes out, the condition that triggered it stays on record, so when a customer asks why a part was rejected, one screen answers.
Deep learning runs the other way. Show it enough good and bad images and the model builds the criteria that separate them on its own, and nobody has to write those criteria down in words. In kitchen terms, a decision you can write as “3 g of salt” belongs to rules, and one you can only write as “until it tastes right” belongs to learning. The hole diameter is written as the number 3.00 ± 0.05 mm, so it sits on the first side, while scratches differ in length, direction and brightness from cover to cover, which puts them closer to the second.
Reading a 100 μm tolerance with a 16.3 μm pixel
How precise the rules can be starts with how many μm one pixel covers on the cover. The sensor is 2,448 × 3.45 μm = 8.45 mm wide and the field of view is 40 mm, so the magnification is 0.211 and one pixel covers 16.3 μm on the cover. To get that magnification with a 25 mm lens, the WD4 from lens to cover has to be about 143 mm (thin-lens approximation). The field of view comes out 33.5 mm tall.
The tolerance band, top and bottom combined, is 100 μm. My rule is to keep measurement resolution at a tenth of the tolerance5 band, 10 μm or finer, so one 16.3 μm pixel is not enough. That is why I use subpixel edge detection6, which reads where a boundary passes between two pixels from the slope of the brightness. Assuming a repeatability of 0.1 pixel gives 1.6 μm, and even six times that, 9.8 μm, stays inside 10 μm. The circumference of a 3 mm hole is 9.42 mm, so about 577 edge points fall on one circle, and when the circle is fitted those points cancel out each other’s random wobble.
Once the numbers get this small, the causes of wobble move outside the algorithm. The hole outline is shot as a silhouette with a backlight7 shining from below, and if the brightness slope at the edge spans 2 pixels with the threshold fixed at half the original brightness, a backlight 10 % brighter moves the edge by 0.09 pixel, or 1.5 μm, and one 10 % dimmer moves it by 0.11 pixel, or 1.8 μm. The diameter measures both edges together, so it shifts by 3.0 to 3.6 μm, roughly a third of my 10 μm criterion. The rule stayed the same; the light that went into the rule moved. So before measuring begins, I fix the backlight brightness and set a brightness reference patch in a corner of the field of view to check on every frame.
16.3μm
Width one pixel covers on the cover
1.6μm
Repeatability assuming 0.1-pixel subpixel reading
3.6μm
Diameter shift when the backlight dims by 10 %
Scratches slip out between the conditions
On the scratch side, the arithmetic holds but the rules do not. A 50 μm scratch spans 3.06 pixels at 16.3 μm, which barely clears my rule that a defect should cover at least three pixels. Under dark-field illumination8, which lights the surface from a low angle, a scratch on a matte surface rises as a bright line on a dark background, so up to this point rules can still catch it.
The trouble is the texture of the cover. The fine pattern cut into the mold also glints here and there under low light, and when those glints line up they look much like a short scratch. Raise the brightness threshold and faint scratches drop out; add a length condition and short, wide scratches drop out; add a direction condition and slanted scratches drop out. Each new condition opens a hole somewhere else. More conditions, more gaps. If months go by holding on with rules while the conditions keep multiplying, that is the signal to change methods.
A trained model learns this pattern as part of normal. It does not need a person to explain in words that this kind of glint is fine; it picks up the look of the pattern itself from images of good covers. If there are no defect images yet, you can start with anomaly detection9, which trains on good images only and marks places that differ from usual. Anomaly detection only says where something differs, though, without telling a scratch from a stain, so judging by defect type comes after defect images have been collected.
Learning is paid for in time spent collecting defect images
The moment learning is chosen, a new line appears on the schedule. Assume a scratch defect rate of 0.5 % and an inspection tact time10 of 2 seconds, and take 300 defect images per type for the first classification model as my rule. Collecting 300 images takes 60,000 covers, which at 2 seconds each is 33.3 hours. It looks like a job of a day or two.
Split the scratches into three types and say the rarest type is 10 % of all defects, and the story changes. Those 300 images of that type need 600,000 covers, which is 333 hours, or 13.9 days running around the clock. Ten times longer. The number that sets the training schedule is the share of the rarest type, and the average defect rate does not decide it. Anomaly detection starting from 200 good images, by contrast, collects its images in 400 seconds, 6 minutes 40 seconds.
With deep learning
It seems inspection starts as soon as the images go in.
If the rarest scratch is 10 %
Collecting 300 images of that type takes 600,000 covers, or 13.9 days at a 2-second tact time.
Put this number on the table in the first setup meeting, and the order follows naturally: hold the line with anomaly detection for the first few weeks, and grow the classification model from the defect images collected in the meantime.
Splitting the work inside one station
On a real station, the work gets split instead of one method being picked. The same camera alternates between a backlight frame and a dark-field frame; the backlight frame finds the center of the reference hole to correct the cover’s position and rotation, and those coordinates cut out the area for scratch inspection and pass it to the trained model. The diameter decision stays with the rules. Setups that hand alignment and measurement to a model as well do exist, but in my judgment those are areas where rules are faster and easier to explain.
| Inspection item | ① Minimum defect size | ② Optical setup · WD | ③ Algorithm parameters · in plain words |
|---|---|---|---|
| Position and rotation alignment | Reference point, so no defect size (circle fitted from about 577 edge points) | Backlight frame, 25 mm lens, WD about 143 mm, field of view 40 × 33.5 mm | Shift and rotation corrected from the hole center and a second hole. Every later decision uses these coordinates |
| Hole diameter Ø3.00 ± 0.05 mm | A tenth of the 100 μm tolerance band = 10 μm (16.3 μm pixel, 1.6 μm assuming 0.1-pixel subpixel reading) | Backlight frame, same lens and WD, brightness reference patch in a corner of the field | Subpixel edges + circle fit, judged at ±0.05 mm. A ±10 % backlight swing spreads into 3.0 to 3.6 μm of diameter |
| Surface scratch | 50 μm wide = 3.06 pixels | Low-angle ring light (dark-field) frame, same lens and WD | Start with anomaly detection on 200 good images, then classify once 300 per type are in. The rarest type sets the schedule |
Set the three rows side by side and the split shows: rules align and measure, and learning takes only the judgment of shape.
When I review a new inspection, I ask four questions in order: can the criterion be written as a number, can hundreds of defect images be collected, can the lighting and position be fixed, and does the decision need to be explained. The more “yes” answers to the first three, the more it leans toward rules, and for an item where the fourth is “yes,” I keep a rule-based reason alongside even when a trained model makes the call.
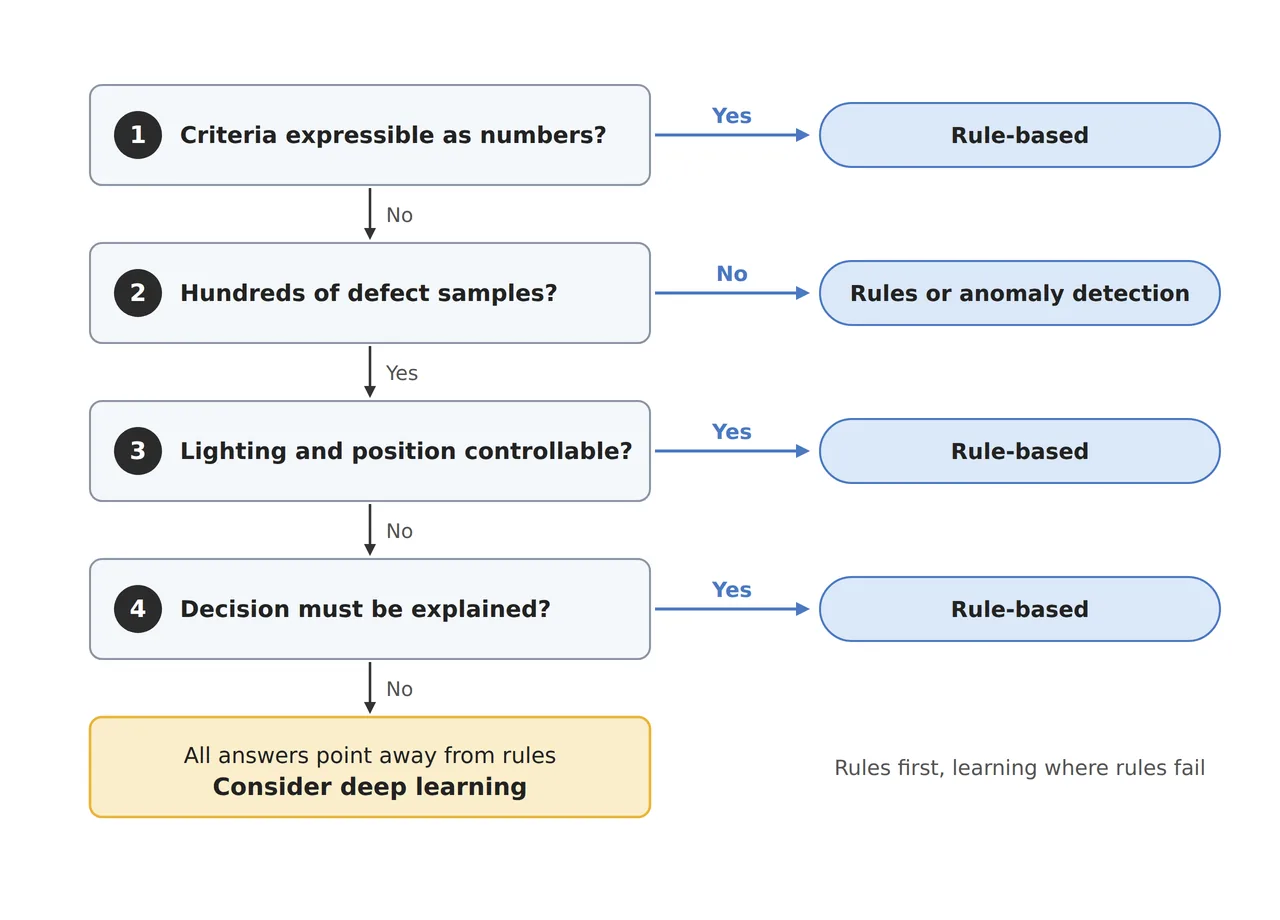
In the flowchart, the path drops to the last box, deep learning, only when none of the four questions points toward rules. The opposite direction is clearly right in some cases. For targets whose normal look varies by nature, such as wood grain or woven fabric, or for lines where frequent product changes make it hard to reset lighting and position every time, sending everything except dimensions to learning from the start carries less maintenance burden. Conversely, a clear-cut decision such as whether a part is present or missing is enough for rules even when it concerns appearance. How cleanly anomaly detection will separate this cover’s mold texture from scratches cannot be guaranteed before a sample test.
Drawing the line between rules and learning with numbers is close to what a vision engineer does every day, and knowing how to do this calculation is useful on both the side that builds equipment and the side that runs it. For a plant weighing the investment, the production time spent collecting defect images can cost more than the software itself, and that time is calculated in advance from the defect rate and the type mix. This article explains technology and is not investment advice. See our Disclaimer.
Field Note
To set up a station for this cover, I would start with a repeat measurement: put the same cover back on the backlight 30 times and measure the diameter each time. I check whether the standard deviation of those 30 values is 1.67 μm or less, so that six times it fits inside 10 μm, a tenth of the tolerance band, and if it overflows, I suspect focus and backlight brightness before the algorithm. On the scratch side, I first spend the 6 minutes 40 seconds it takes to shoot 200 good covers, and check how far the mold texture pushes up the anomaly score in those images.
Field Checkpoints
Once 30 repeat measurements and 200 good images have checked the assumptions behind the two calculations, I turn to the questions below.
- Is a WD of about 143 mm (25 mm lens, 40 mm field of view) available after adding the fixture and backlight heights? (whether the camera has a place to stand at that height)
- Is the standard deviation of 30 repeat diameter measurements 1.67 μm or less? (whether the rules read a tenth of the tolerance band)
- Have you measured how many μm the diameter moves when the backlight brightness changes by ±10 %? (compared with the calculated 3.0 to 3.6 μm)
- Have you counted what share of all defects the rarest scratch type makes up? (whether that share sets the training schedule)
- Have you checked with samples how often anomaly detection trained only on good images calls the mold texture a scratch?
- Have you left the items whose decisions must be explained to customers on the rule side?
Frequently Asked Questions
How do anomaly detection and a classification model differ?
Anomaly detection learns from good images only and then marks places that differ from usual with a score. It has the advantage of starting when there are almost no defect images, but it does not name a defect as a scratch or a stain. A classification model learns from defect images of each type and names them, but it needs enough images per type. A common setup chains the two, with anomaly detection picking candidates and classification naming them.
What is the signal to switch from rule-based inspection to deep learning?
When the conditions keep growing to catch the same defect, and every new condition creates misjudgments somewhere else, it is time to switch. If instead the conditions have stayed the same for months and misjudgments cluster only on days when the lighting or position wobbled, fixing the optical setup first is faster than changing methods.
Glossary
- [1] Deep learning DL
A multi-layer neural network approach that learns decision criteria on its own from many example images, with no rules written by people. ↩ - [2] Rule-based rule-based inspection
An approach that judges with numeric conditions people set, such as a brightness threshold, an area or a length. The condition that fires becomes the reason for the decision. ↩ - [3] Blob analysis blob analysis
A technique that finds connected clumps of pixels in a thresholded image and measures their area, length and position. ↩ - [4] WD working distance
The distance from the lens to the surface being inspected. The values in the text use a thin-lens approximation measured from the lens center. ↩ - [5] Tolerance tolerance band
The range of difference allowed from the design value. For 3.00 ± 0.05 mm, the tolerance band, top and bottom combined, is 0.10 mm, or 100 μm. ↩ - [6] Subpixel edge detection subpixel edge detection
A method that traces the brightness change across pixels near a boundary to read where the boundary passes between pixels, finer than one pixel. ↩ - [7] Backlight backlight
Lighting that shines from behind the object to capture its outline as a black silhouette. Mainly used to measure holes and outer dimensions. ↩ - [8] Dark-field illumination dark-field illumination
Lighting from a low angle that keeps flat surfaces dark and makes only light-bending places, such as scratches and steps, appear bright. ↩ - [9] Anomaly detection anomaly detection
An approach that learns from good images only and then marks places that differ from usual with a score. It does not sort defects by type. ↩ - [10] Tact time tact time
The time allotted for one part to pass through a process. The text assumes 2 seconds per cover. ↩
References
- MVTec Software, The MVTec Anomaly Detection Dataset (MVTec AD) (an unsupervised anomaly detection dataset with defect-free training images and test images that include defects, presented at CVPR 2019)
- Formulas: magnification m = sensor width ÷ field of view, pixel resolution = field of view ÷ horizontal pixel count, WD ≈ f × (1 + 1/m), edge shift = ramp width × |0.5 − 0.5 ÷ brightness ratio|, diameter shift = 2 × edge shift, covers needed = target defect images ÷ (defect rate × type share)
Related reading — Overdetection or Missed Detection, Which One Costs More? · Can Five Defect Samples Stand Up a Few-Shot Anomaly Detection Line? · When 3D+AI Inspection Answers the Shape Defects 2D Can’t Catch

Noctvision
An engineer who has handled mechanical design and project management for production equipment since 2005. Here I work through the cameras, lenses and lighting that go into equipment with formulas and public data, and record the assumptions and sources alongside the numbers.


You May Also Like
Can One Focus Plane Keep Parts of Every Height Sharp?
Camera Interface Bandwidth Determines Resolution